The Safety-Disclosure Gap: What 857 Chinese Model Releases Mean for Enterprise Approval
ODA3 Institute | Evidence reviewed through 13 October 2026
An enterprise can buy a capable model without acquiring enough evidence to justify giving it access to sensitive data or consequential actions. Public safety documentation helps, but the decision turns on whether the evidence supports the system the enterprise will actually operate.
A recent disclosure study makes that distinction concrete. SemiAnalysis reports reviewing 857 releases from nine Chinese developers, spanning 2021 to 15 September 2026. It reports 31 releases with developer-published safety results, nine available at launch. The source describes a model-specific matching method and warns that an unsuccessful public-document search does not establish that testing never occurred. ODA3 Institute inspected the published account; it did not reconstruct the inventory. S1
The leadership decision is therefore specific: what evidence must exist before this deployment receives these permissions, and who can accept the uncertainty that remains? A disclosure percentage cannot answer it.
What the study establishes—and where the count needs care
The report was published on 8 October 2026. Reuters coverage dated 9 October reports the same headline count; that coverage is corroboration of reporting, not independent replication. S1S2
The published categories require care. SemiAnalysis places ten releases in an assertion-only category and three in a press/investor-only category, alongside its 31-result category and 813-disclosure-absent category. Within the 31, six have unresolved timing or model correspondence. Consequently, 813 must not be described as every release lacking a matched result. The reported categories sum to 857. This arithmetic check does not validate any underlying row classification. S1
Counting separate sizes and snapshots changes the denominator; without an alternative inventory, the size of that sensitivity has not been measured here. These figures concern public evidence in a defined population. They do not measure production failure, private testing quality or relative safety across countries. A buyer should use the finding as a reason to examine evidence access, rather than as a vendor exclusion score.
SemiAnalysis also reports that disclosed results concentrated on harmful-output, refusal and jailbreak tests, with only three addressing cyber-offence or biological risk; this describes the scope of the reported evaluations, not the effectiveness of a downstream deployment. S1
Three questions that procurement must keep separate
What did the provider evaluate? A report may concern harmful outputs, refusal behavior or a particular capability. Procurement needs the protocol, tested model, conditions, limitations and adverse findings. “Safety evaluated” is an assertion until the relevant result can be examined.
What does that evaluation cover here? The buyer adds retrieval, identities, tools, data and business consequences. Evidence about model behavior cannot by itself establish that a document connector respects customer permissions or that a payment tool rejects unauthorized instructions. A provider evaluation can be useful without being sufficient for either claim.
Can the conclusion be independently challenged? Reviewers need enough access to question the method, inspect artifacts and, where feasible, repeat relevant tests. Confidential access can serve this purpose. Public availability and independent verification are different properties.
Evidence can be documented and reproducible yet still fail to support the deployment decision. A beautifully documented test may examine the wrong deployment. An independently repeated test may rely on the same unrepresentative dataset. Evidence sufficiency requires separate checks that cannot compensate for one another.
NIST’s AI RMF Core supports attention to deployment context, documented measurement and leadership accountability; its accompanying Playbook is voluntary guidance. Neither establishes that following a framework proves a particular system safe. S3S4
Evidence responsibilities depend on the delivery route
The model’s delivery route changes the evidence a buyer can obtain and the components it controls. These are conditional architecture considerations, not findings about the developers in the study.
| Delivery route | Evidence responsibility | Change and correspondence concerns |
|---|---|---|
| Hosted API | Provider supplies model evidence; buyer establishes its integration and workflow behavior. | An alias may conceal model or serving changes; obtain version information and document its limits. |
| Self-hosted weights | Provider evidence remains relevant; operator validates weights, serving stack, guardrails and deployment. | Pinned weights stabilize one component. Libraries, adapters, policies and serving configuration can still change. |
| Embedded vendor product | Vendor explains the model and wrapper; buyer examines configuration and its permitted workflow. | Model identity and relevant settings may be hidden. Seek enough access to evaluate material claims. |
Evidence should cover four related layers: provider model, integration, business workflow and ongoing operation. They locate the evidence work; they are not a maturity scale. A model report can inform integration tests, but cannot replace them. A deployment test can establish a bounded access-control result while leaving the provider’s training or private evaluation practices unknown.
Responsibilities do not transfer automatically because public documentation is absent. Providers and product vendors remain responsible for their own representations and obligations; the deploying enterprise must establish the basis for its use decision. It can obtain assistance from providers and independent reviewers while retaining accountable ownership.
Public disclosure can include methods, artifacts and independently repeatable tests. It can therefore support independent reproduction, not only a documented result. What it cannot automatically establish is correspondence to a different downstream system. Documentation, reproducibility, deployment relevance and independence should be examined separately.
Four checks before evidence can support a deployment decision
The following is an ODA3 Institute analytical proposal, not a new standard or a validated scoring instrument.
| Check | What must be established | What cannot substitute |
|---|---|---|
| Correspondence | Evidence covers the model and relevant system configuration, or an explicit applicability argument explains differences. | A family name or a report for an earlier endpoint. |
| Coverage | Evaluation addresses the material hazards and business requirements for the proposed use. | Numerous unrelated benchmarks. |
| Integrity | Artifacts have attributable origin, controlled versions and a documented chain of handling. | A hash without trustworthy acquisition or authorship. |
| Challengeability | An appropriately independent reviewer can scrutinize the method and relevant artifacts; testing limits are explicit. | An independence label or a summary presentation alone. |
These checks should apply to each material claim. A gap in one claim should not be concealed by a high aggregate percentage across easier claims. For example, accurate summarization does not compensate for an unverified restriction on customer-data access.
Correspondence deserves particular care for hosted models. The provider may expose a stable alias without a verifiable immutable checkpoint. Record what is known: endpoint, returned model identifier, request settings, provider change notices and test window. If the underlying model cannot be pinned, state that limitation and shorten the validity of conclusions where appropriate. Behavioral canaries may detect some changes; they cannot prove that the model remained unchanged.
Examine the boundary where the model can create effects
Consider a claims-support assistant that can search files and draft correspondence. Its model may refuse a direct request for another customer’s claim. That observation says little about whether an attachment search route can retrieve the same record.
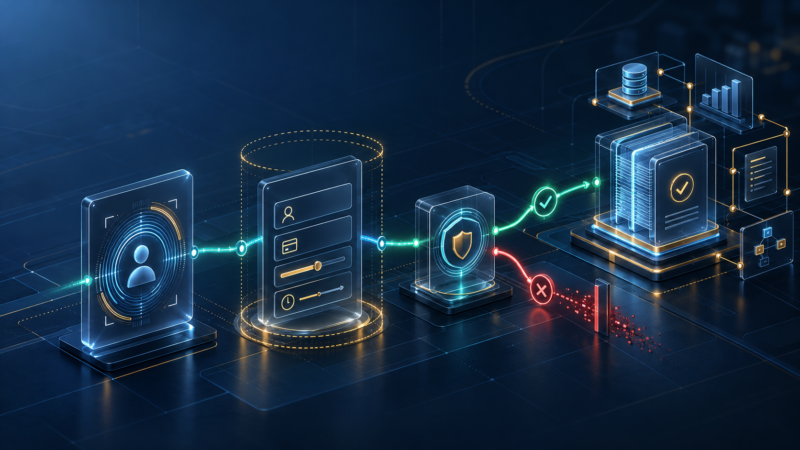
A defensible design places authorization at the retrieval service and the action boundary. The service should evaluate the authenticated principal, tenant, resource, permitted operation and relevant policy state. Model-generated text should not establish entitlement. Every equivalent access route—including cached results and delegated calls—belongs in the boundary analysis.
Revocation requires its own test. A user whose access was removed may still have a live session, cached retrieval result or delegated token. The architecture must specify when revocation takes effect and how stale authority is rejected. A check at the beginning of a long-running task does not establish authority at a later consequential action.
The ODA3 analytical chain connects the decision to its support:
Requirement → Control → Evidence → Provenance → Verification → Finding → Bounded Assurance
For the requirement “the assistant must not expose another tenant’s claim,” the control might be server-side resource authorization. Evidence should include the policy and configuration, adversarial requests, observed service decisions and the returned data or downstream effects. Provenance connects those artifacts to the tested environment and time. Verification examines whether denied requests actually prevented the prohibited effect and whether alternate routes were tested. The finding states what that evidence supports within the examined scope.
A denial log proves that a component recorded a denial. To establish prevention, examine whether the protected record was returned through another route, emitted to another destination or already present in the agent’s context. Log correlation assists reconstruction; it does not automatically establish causality or completeness.
An illustrative approval decision
The following scenario is constructed. It is not an observed incident or a finding about a developer in the study.
An insurer receives extensive public benchmarks from Provider A, but cannot establish their correspondence to its hosted endpoint. Provider B offers less public material and confidential access to evaluation records for the relevant release. Neither fact alone settles selection.
The insurer requests equivalent evidence from both providers and tests its own retrieval integration. A synthetic cross-tenant attachment test reveals unauthorized retrieval through a connector. The model’s direct refusal remains intact, but the system requirement fails in that tested configuration.
Management should restrict the affected route, preserve artifacts and verify the repair across equivalent paths. Sensitive deployment remains deferred until the required access boundary is evidenced. A drafting-only pilot using synthetic or approved non-sensitive data may proceed if its separate scope and controls justify it. Replacing the model without repairing the connector would leave the demonstrated mechanism unresolved.
The final finding should describe the tested configuration, observed effect, repair and residual limitations. It should not become “Provider B is safe” or “all disclosure-poor models are unsafe.”
What leadership should authorize
Leadership should establish evidence requirements before supplier selection and delegate acceptance within explicit limits. Business owners remain accountable for consequences; technical teams establish control behavior; procurement secures access to provider evidence; risk functions challenge residual uncertainty. Independent assurance evaluates what the assembled evidence is sufficient to support.
| Decision | Accountable function | Evidence needed | Response to a material unresolved gap |
|---|---|---|---|
| Permit sensitive data | Business owner, with CISO and risk review | Resource authorization, segregation and disclosure tests covering relevant routes. | Remove sensitive data or defer the use. |
| Permit consequential tools | Business owner and security architecture | Execution-time authorization, delegation limits, revocation and independent effect observations. | Disable the affected action or retain a verified approval barrier. |
| Accept the supplier arrangement | Procurement and legal | Evidence access terms, version/change information and incident cooperation arrangements. | Negotiate access, narrow scope or select an alternative. |
| Accept residual uncertainty | Designated risk authority | Named Unknowns, consequence analysis, controls, expiry and withdrawal triggers. | Escalate rather than convert uncertainty into a pass. |
These are proposed operating decisions. Applicable legal duties require separate jurisdiction- and use-specific analysis. Neither the study nor this article determines that any supplier is noncompliant.
For the CFO, the comparison is total cost of the permitted workflow: inference and licensing, evidence access, integration controls, testing, monitoring, change review, fallback capacity and operational restrictions. Evaluate those costs against measured business benefit and feasible alternatives. There is no defensible universal loss probability or cost multiplier derived from disclosure frequency.
Confidential evidence access also has costs. Supervised review may limit retention or reproduction. Disclosure of complete attack datasets can create misuse or intellectual-property concerns. Agree what the reviewer may inspect, retain and challenge, and describe the resulting assurance limits. A contractual audit right has practical value only if it can obtain relevant evidence in time for the decision.
Build a reviewable evidence record
Start with a bounded deployment claim and its prohibited outcomes. Record the model route, identity mechanism, retrieval sources, tools, permissions, policy versions and update conditions. Where a supplier cannot identify a component precisely, preserve the uncertainty instead of creating an artificial immutable identity.
Design tests around the actual effect boundary. Use synthetic data and controlled destinations where possible. Exercise direct and indirect prompt injection, alternate connectors, cross-tenant requests, delegated authority, revocation during a task, retries and cached access as relevant. Include authorized tasks to detect controls that prevent useful work indiscriminately. State sample selection, repeated-run conditions and coverage limits for stochastic behavior.
Observe the outcome through a channel that does not depend entirely on the component under test: protected-service records, controlled output capture or independently instrumented side effects. Review correlated traces, discrepancies and missing observations. Preserve positive, negative and inconclusive results together.
Maintain distinct records for finding and decision. Supported, Partial, Gap and Unknown can describe evidence sufficiency for a defined claim under explicit local rules. An unavailable record may leave the control Unknown while creating a Gap against an evidence-delivery requirement. Neither label alone decides deployment. The accountable authority records approval, restriction or deferral and its rationale.
Bind approval to the examined scope and validity period. Reassess after material model, connector, permission, policy or data changes, and after failures that challenge the claim. Record which findings remain applicable. Monitoring and incident response support this process but cannot replace missing pre-deployment evidence for a critical property.
This article uses ODA3’s evidence discipline without asserting a detailed framework mapping. Missing disclosure is an evidence issue; it is not by itself an AI incident. Incident taxonomy, response methods and physical-system assessment belong in scope only when the actual deployment or observed event requires them.
Notably Absent
ODA3 Institute did not reproduce the release inventory, audit individual historical disclosures, inspect confidential developer testing or evaluate the nine developers’ production systems. No matched cross-country comparison or empirical connection between disclosure frequency and operational harm was established.
The category reconciliation is based on the published narrative, not row-level reconciliation. The release inventory was not available to this review; its availability elsewhere or on request has not been established. The unreviewed paywalled conclusion is outside the evidence base. Reuters’ search-accessible report corroborates the headline; the full Reuters page was not retrievable during this review. No detailed ODA3 control mapping, certification conclusion or claim of tested effectiveness is made.
The four evidence checks, decision matrix and operating procedure are analytical proposals. They have not been validated as predictors of incident reduction or procurement outcomes. The illustrative insurer scenario supplies no empirical result. No financial return, incident probability or universal minimum testing threshold has been measured here.
Public safety reporting improves visibility. Deployment approval still needs a defensible connection between the claim, the configured system, the observed controls and the remaining uncertainty. That connection is what management must be able to show when it grants an AI system access or authority.
References and evidence notes
[S1] Original research; figures Reported. SemiAnalysis, Mark Chen, Doug and Dylan Patel, Beijing Will Not Pace the Frontier: China’s Speed-First AI Safety Regime, 8 October 2026. Published account inspected 13 October 2026; underlying inventory not replicated. Read the research.
[S2] Secondary reporting; retrieval limited. Reuters, China AI developers publish safety tests for just 3.6% of model releases, report finds, 9 October 2026. Search-accessible text inspected 13 October; full page unavailable. Read the report.
[S3] Official framework text; Verified as documentary guidance. NIST, AI RMF Core, excerpt from AI RMF 1.0 (2023), inspected 13 October 2026. Contextual support, not a legal obligation or validation of this article’s proposed method. Read the Core.
[S4] Official guidance; Verified as voluntary. NIST, AI RMF Playbook, inspected 13 October 2026. Read the Playbook.
© 2026 ODA3 Pvt Ltd. Published by ODA3 Institute.
Methodology note
Public-source analysis; published category arithmetic checked (31 + 10 + 3 + 813 = 857); inventory not independently reconstructed; four non-compensatory evidence checks are ODA3 analytical proposals; illustrative insurer case is hypothetical.
Notably Absent
No row-level release-inventory reproduction, confidential developer tests, nine developers’ production assessments, matched cross-country comparison, empirical link to operational harm, full Reuters page, unreviewed paywalled conclusion, validated procurement-outcome predictors or tested control effectiveness.