Search the archive here. Open a publication from its result card, without visiting a second archive page.
About this catalogue
Search published articles by title, publication ID or recorded category. Filter by document family or year, then open the published article from its result card.
Search results are retrieval matches, not evidence-tier judgments.
Open to read. A published article does not by itself establish an assessment or certification of a system.
127 matching publications.
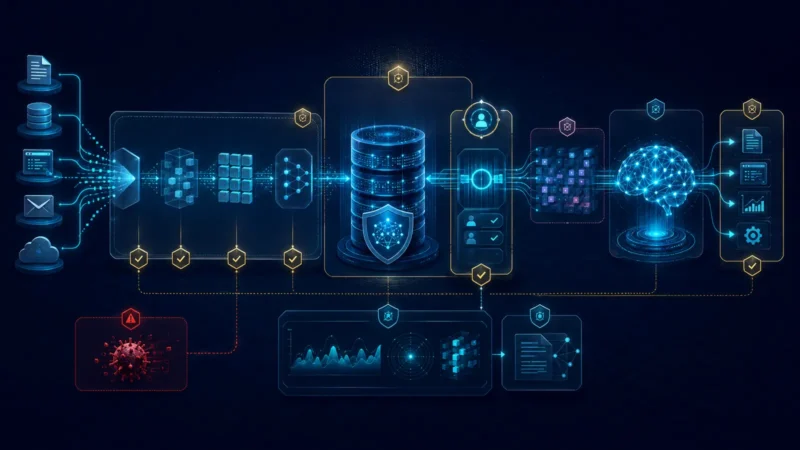
ODA3-2026-07-CHT-SEC-013
17 Jul 2026
Retrieval-augmented generation creates a security boundary across sources, ingestion, retrieval, context, generation and downstream action. Protecting only the model or vector database leaves the rest of that boundary exposed.
Read publication →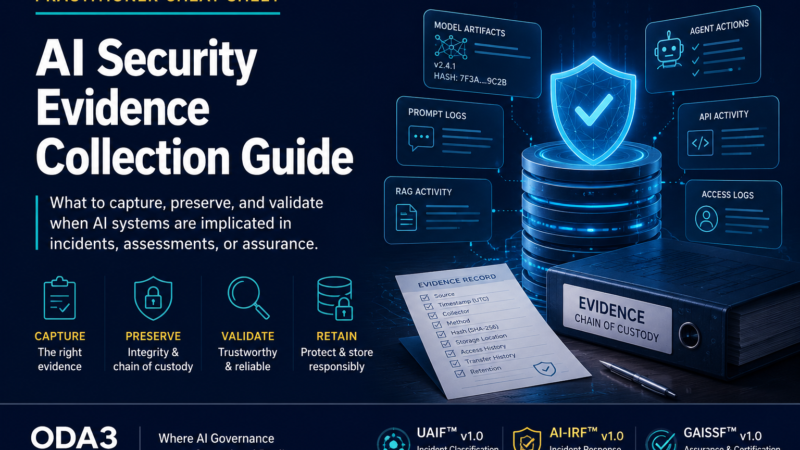
ODA3-2026-07-CHT-SEC-009
15 Jul 2026
Most organizations discover their AI evidence gaps mid-incident, mid-audit, or mid-assessment—when it is too late to recover what was never logged.
Read publication →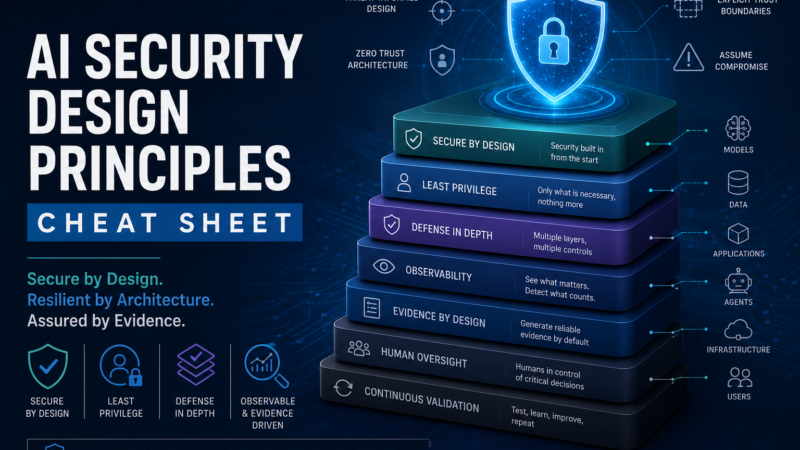
ODA3-2026-07-CHT-SEC-008
14 Jul 2026
Nine design principles for building enforceable security into AI systems before deployment.
Read publication →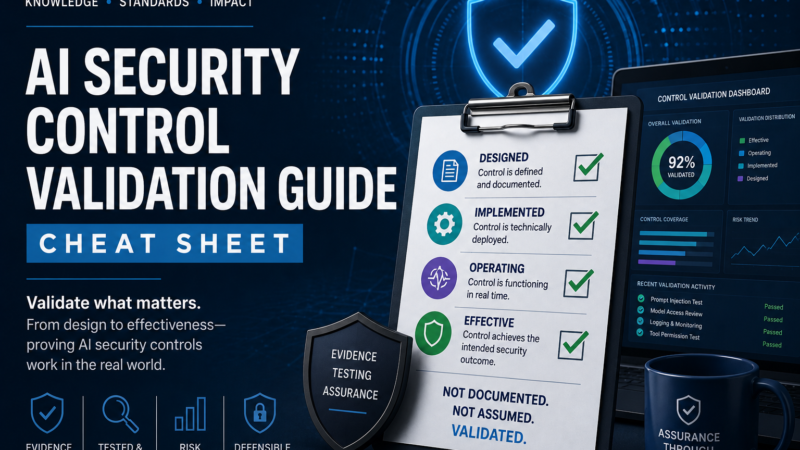
ODA3-2026-07-CHT-SEC-007
13 Jul 2026
A practical method for proving that documented AI security controls operate as intended.
Read publication →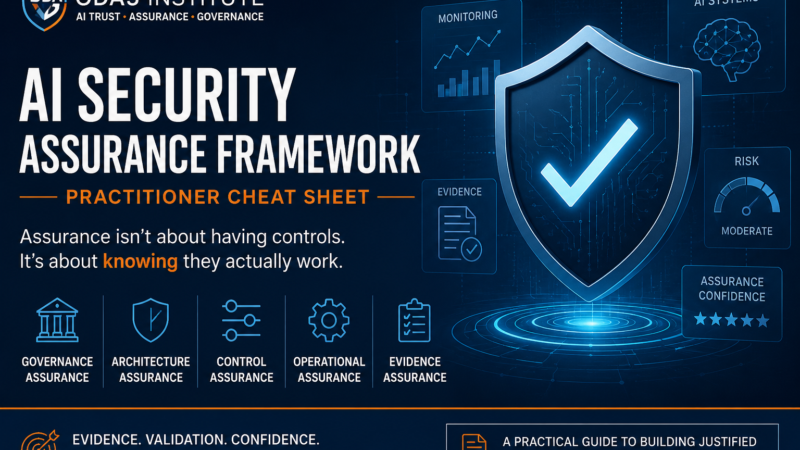
ODA3-2026-07-CHT-SEC-006
10 Jul 2026
A structured way to connect governance claims, operating controls, evidence, and bounded conclusions.
Read publication →
ODA3-2026-07-CHT-SEC-005
9 Jul 2026
Placing controls at the right layer across model, retrieval, agent, tool, and enterprise boundaries.
Read publication →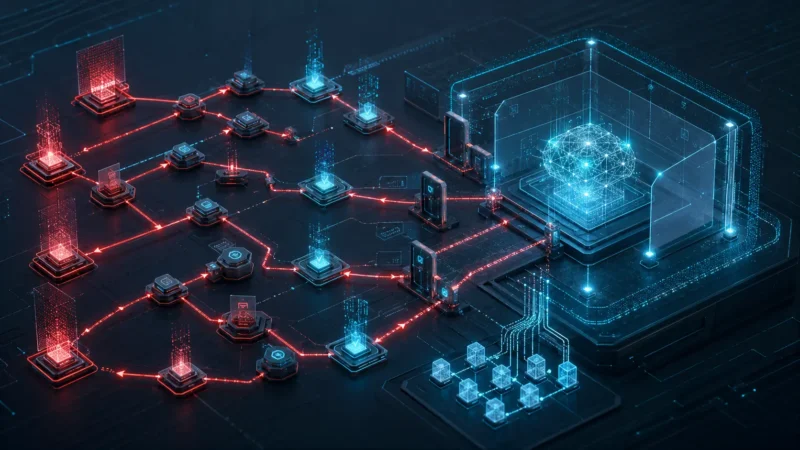
ODA3-2026-07-CHT-SEC-003
8 Jul 2026
A structured, authorized and evidence-producing method for adversarial testing of AI systems.
Read publication →
ODA3-2026-07-CHT-SEC-004
8 Jul 2026
A routing matrix for distinguishing harmful system behaviour from adversarial compromise and overlap.
Read publication →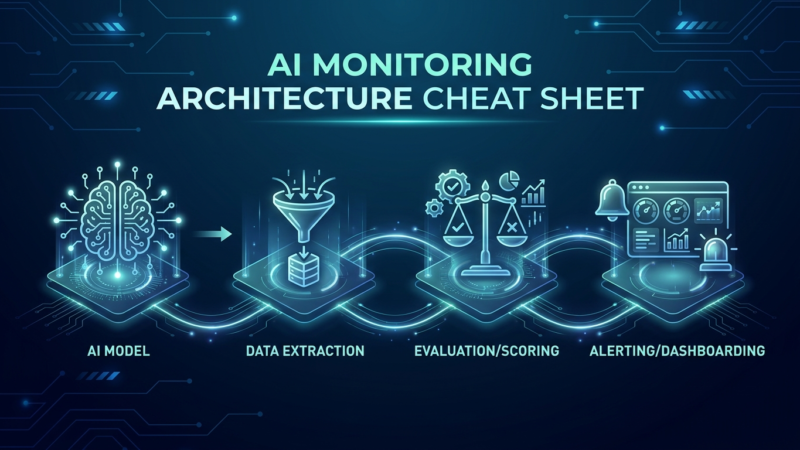
ODA3-2026-07-CHT-SEC-002
7 Jul 2026
Monitoring model behaviour, retrieval, agent actions, tool use, and infrastructure as one evidence chain.
Read publication →
ODA3-2026-07-CHT-SEC-001
6 Jul 2026
A layered control model for reducing prompt-injection impact across AI applications, RAG and agents.
Read publication →
ODA3-2026-07-TCR-SEC-004 / ODA3-2026-07-EXB-SEC-005
1 Jul 2026
Q2 evidence indicates that material AI security impact is shifting from model outputs toward authorized actions.
Read publication →
ODA3-2026-06-DP-009
17 Jun 2026
ODA3 defensive publication establishing prior art for Dominant-Harm-Anchored Severity Scoring Engine for AI Incident Classification with.
Read publication →