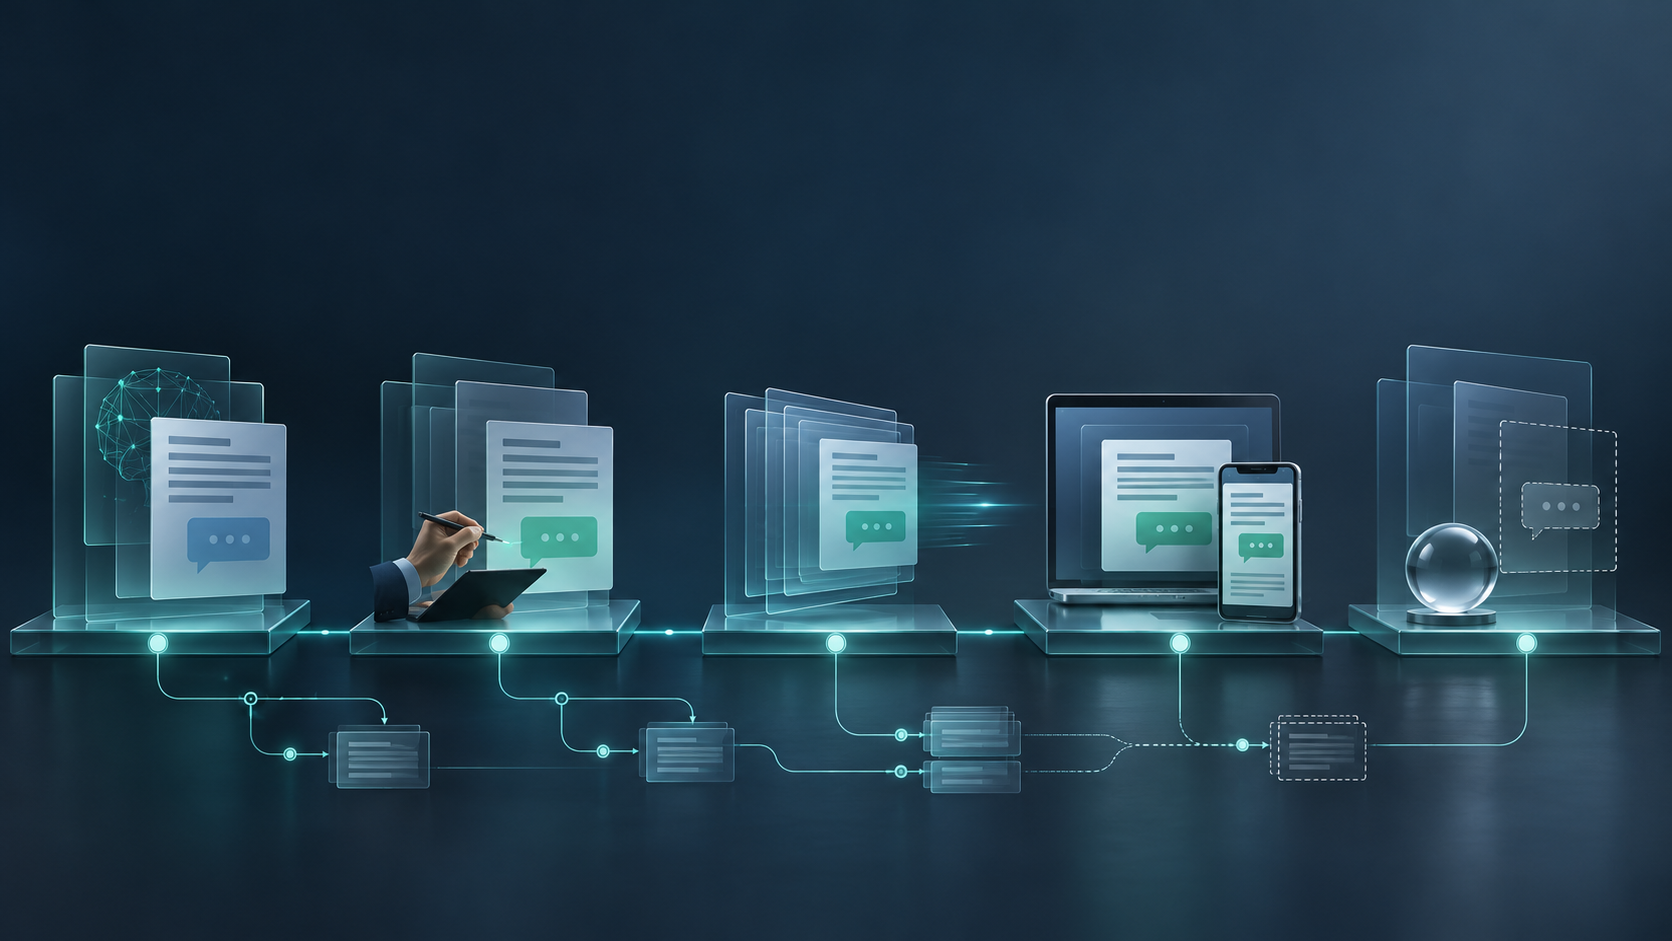
The text an AI generates, the version a person approves and the message a recipient receives may differ. A defensible account needs evidence across those hand-offs, and a communication record alone does not prove reliance, liability or insurance coverage.
Executive takeaways
- Reconstruct the communication, not just the model output. Generation, approval, dispatch, receipt and reliance are separate propositions, each supported by different records.
- Test the account, not only the paperwork. Link versions, authorisations, channel events and exceptions, and look for evidence that could disprove the organisation’s version of events.
- Keep legal and insurance conclusions separate. A clearer factual record may help an organisation or insurer assess an event. It cannot determine loss, liability, policy terms or payment.
The decision: can the organisation establish what reached the recipient?
An AI assistant drafts advice for a customer, and an employee edits and approves it. A delivery service sends the message. The customer later alleges that a misleading statement caused financial loss. The model log holds one version, the approval register another, and the customer’s copy may reflect later changes.
Management has to decide whether the organisation can show which version was authorised, dispatched and received, and say what remains unknown. A model-quality evaluation or an AI policy cannot establish that a communication took place, and a delivery confirmation does not show what the person read.
This is an operational-assurance question. Define the claim, examine the controls meant to preserve the record, verify what the evidence supports and disclose where the chain breaks.
An instructive case, with important limits
In Moffatt v. Air Canada (2024 BCCRT 149), British Columbia’s Civil Resolution Tribunal found negligent misrepresentation. Air Canada’s website chatbot had told a customer that a bereavement-fare reduction could be requested within 90 days of the ticket being issued. That was contrary to the airline’s own bereavement-travel webpage. The tribunal ordered Air Canada to pay $812.02 in total, comprising $650.88 in damages, $36.14 in pre-judgment interest and $125 in tribunal fees. [4]
The record is the instructive part. The customer supplied a screenshot of the chatbot response, as described in the decision and contemporaneous legal analysis. Air Canada gave no information about the nature of its chatbot. It relied on tariff terms it did not produce, and that defence failed. [4]
The limits are material. This was one small-claims decision in one Canadian province. It concerned a chatbot answering customers directly, not a human-reviewed drafting and dispatch workflow, and it raised no insurance question. The narrow lesson is that the organisation should hold its own record of what it presented to a customer. The tribunal did not prescribe any particular evidence method, and liability tests differ by jurisdiction.
From governance requirements to evidence of behaviour
The US National Institute of Standards and Technology released its AI Risk Management Framework 1.0 on 26 January 2023. The framework is intended for voluntary use and is currently being revised. It neither sets insurance contract terms nor mandates the message-reconstruction approach described here. [1]
ODA3 Institute’s evidence discipline keeps a source record, its basis, the verification performed and its limits distinct. Its operational assurance chain runs Requirement → Control → Evidence → Provenance → Verification → Finding → Bounded Assurance. An examination therefore starts with the precise proposition to be tested, not with the fact that an organisation has adopted a framework. [2]
This article addresses a narrower question than ODA3 Institute’s analysis of AI insurance submissions, which examines actors, causal contribution and harm more broadly. Here the question is whether the record supports a claimed communication event. [3]
Five evidence stages that cannot be assumed equivalent
1. Generated. The AI application’s record may establish an output, the model and application version, and the generation context. It does not show that the output was approved or sent.
2. Approved. A reviewer or authorised workflow may accept or modify a particular version. The sign-off must be linked to that exact artefact and checked against the approver’s actual authority. Any later changes need separate tracing.
3. Dispatched. An application hands a payload to a mail, messaging or API provider. A queued, accepted or “sent” event proves only what the recording system observed, not downstream delivery.
4. Received. Delivery events and recipient-side records may show what reached a device, inbox or application. A matching content hash is useful only when the hashing and collection contexts are understood. Neither a hash nor a delivery receipt shows that a person viewed the material.
5. Relied upon. Establishing what a recipient read, understood or acted on may require correspondence, transaction records or witness evidence. Even proven reliance does not by itself establish compensable loss, legal liability or insurance coverage.
No single identifier has to run through every system. A traceable transaction ID or a documented mapping between identifiers can be enough for a defined inquiry. The trace must still account, where material, for retries, failed or cancelled sends, corrections, timestamps and transformations by the provider. Retention and disclosure must comply with applicable privacy, confidentiality and legal requirements.
What an examiner can and cannot conclude
| Examination question | Evidence to examine | What it may support | What it does not establish |
|---|---|---|---|
| What was generated? | Output record, system and version context | A recorded output under stated conditions | Approval or communication |
| What was authorised? | Version history, approval event, authority record | Approval of a specified artefact | Absence of later editing or bypass |
| What was dispatched? | Outbound payload or integrity record, channel acknowledgement, identifier mapping | A defined hand-off or transmission attempt | Delivery of identical content |
| What was received? | Delivery status and lawful recipient-side copy, if available | Content correspondence and delivery within examined boundaries | Human reading or reliance |
| Did controls operate? | Configuration, approval enforcement, exceptions, bypass attempts, transaction traces | Operation of selected controls within the sample and period | Universal effectiveness or future reliability |
An independent examination needs stated criteria, a system boundary, an observation period, provenance, a record of the verification performed and declared exclusions. It should look for contradictory evidence as well as supporting records. Examples include an approval timestamp after dispatch, an attachment hash that does not match, a retry that carried different content, or a provider log inconsistent with the organisation’s account.
Where a record is unavailable, the related proposition is ordinarily Unknown. A Gap finding requires a defined requirement and evidence that it was not met. A missing record alone does not show that the AI system or a control failed. This article reports no examination or formal finding on a real deployment.
Illustrative scenario — synthetic, not an examined incident
A professional-services firm uses AI to draft a recommendation, and the original output includes a qualification. A reviewer approves version B. The gateway keeps a record of the outbound event but not the attached document. Version C is later sent as a correction. The client alleges that the first message made an unconditional recommendation that influenced a costly decision.
The model record establishes the generated version, and the approval record establishes version B. The gateway shows that an outbound event occurred. None of these, alone or together, establishes which attachment the client received first, whether the client read it or why the client acted.
Alternative explanations must also be tested: an edit after approval, a substituted attachment, a failed first send, forwarding on the client side, confusion with version C, or an unrelated reason for the client’s decision. No explanation is presumed, and no insurer response is assumed.
The organisation and the insurer need different evidence
An underwriter assessing a prospective exposure might ask which AI-assisted communications are consequential, how approvals are enforced, whether exceptions are recorded and what changes when the system or provider is updated. A claims handler examining an actual allegation might instead need the disputed wording, the material dates, the recipient’s evidence and the alternative explanations. These are possible lines of inquiry, not established insurer requirements.
The organisation should supply a bounded record: what existed, how it was preserved, what was examined, what is missing and which interpretations remain open. Management owns its controls, records, representations and disclosures. An independent examiner assesses whether specified evidence is sufficient. Insurers decide underwriting and contractual matters, and legal responsibility depends on the facts and the applicable law.
In the US, Verisk has introduced optional generative-AI exclusion endorsements for the ISO commercial general liability programme, with a January 2026 edition date. [5] That shows why contractual precision matters. It is not evidence that any particular insured carries such an endorsement, or that one would apply to the scenario above. General liability wording is not interchangeable with professional indemnity, technology errors-and-omissions or cyber wording. The issued contract, its schedules and endorsements, and the actual circumstances govern.
The evidence cuts both ways. A reconstructed trail could show that disputed language was added by a person after generation. It could equally show that AI-produced text reached the customer unchanged. Either result could clarify a factual dispute without settling causation, responsibility, whether an exclusion applies or whether a claim is paid. This is ODA3 Institute’s analysis, not an observed insurer outcome.
Insurability relevance: conditional. Better records may reduce uncertainty about an event or a control. However, no insurer has validated this reconstruction method, and no premium, acceptance, capacity or claims advantage has been shown. A plausible information benefit is not evidence of lower loss frequency or a more insurable exposure.
Decisions for the C-suite and Board
| Action | Accountable owner | Decision or evidence required | Reassess when |
|---|---|---|---|
| Identify consequential AI-assisted external communications | CRO and business owner | Scope, recipients, foreseeable reliance and plausible loss pathways | Use cases or reliance conditions materially change |
| Test a bounded communication chain | CISO and technology owner | Authorised sample linking output, approval, dispatch and available receipt evidence | Channel, vendor, controls or versions change |
| Define lawful preservation and access | General Counsel with records and privacy leads | Retention, collection integrity, legal hold, confidentiality and access restrictions | Law, contract or dispute posture changes |
| Separate control operation from assurance conclusions | Executive risk sponsor | Criteria, evidence owner, independent examiner where warranted, limits and exceptions | Proposed reliance exceeds the examined scope |
| Test insurance representations against actual terms | Head of insurance or risk transfer | Issued wording, schedules, endorsements and specific insurer questions | Policy terms or material facts change |
The Board’s question is precise: which consequential communications can the organisation reconstruct, which can it not, and what operational change follows? More telemetry does not by itself make better evidence. What matters is collection quality, provenance, linkage and the strength of verification.
Notably Absent
No real production communication chain, insured event, loss, claim decision or independent examination was analyzed for this article, and the synthetic example provides no empirical finding. The sources examined contain no evidence that an insurer has accepted this method, reduced a premium because of it, or paid or denied a claim on this basis. That is not proof that no such outcome has ever occurred.
Moffatt is not an insurance decision and does not validate this method. The Verisk context concerns optional general liability endorsements as described in published trade reporting. No issued policy or full endorsement text was examined. No general conclusion is drawn about the admissibility of electronic records, legal liability, market-wide practice or the accumulation of losses across a portfolio.
No ODA3 Institute client engagement, proprietary operational dataset, certification, insurer endorsement or real assurance result is claimed. Whether a record is sufficient in a real dispute depends on its authenticity, its completeness, the legal context and the decision under consideration.
Conclusion
A model log describes what an AI system generated. It does not prove what an organisation approved or sent, or what a recipient received. A credible evidence programme tests those transitions in a consequential workflow and describes the missing links. When insurance or liability questions arise, those records may clarify the account of an event, but they do not decide the legal or contractual result.
Interest disclosure: ODA3 Institute develops evidence-oriented AI assurance methods and therefore has an institutional interest in the value placed on such evidence. References [2] and [3] are its own publications. No external validation of the method is claimed.
References
[1] National Institute of Standards and Technology. AI Risk Management Framework. AI RMF 1.0 released 26 January 2023; page updated 13 August 2026. Accessed 5 November 2026.
[2] ODA3 Institute. Shared Evidence Discipline. Accessed 5 November 2026.
[3] ODA3 Institute. AI Insurance Submissions: Evidencing Actors, Causation and Harm, ODA3-2026-10-INS-119, 4 November 2026. Accessed 5 November 2026.
[4] Civil Resolution Tribunal (British Columbia). Moffatt v. Air Canada, 2024 BCCRT 149, reasons issued 14 February 2024, paras 14–15, 21, 31–32, 44. Tribunal decision · CanLII. Accessed 5 November 2026.
[5] Germond, N. Verisk to Roll Out New General Liability Exclusions for Generative AI Exposures. Independent Insurance Agents & Brokers of America, 21 October 2025. Accessed 5 November 2026.
© 2026 ODA3 Pvt Ltd. Published by ODA3 Institute. This article is research analysis, not legal, insurance or underwriting advice.
Methodology note
Source-based editorial analysis, five-stage communication-evidence model, synthetic scenario, alternative-explanation testing and bounded insurability assessment. No real system examined.
Notably Absent
This analysis examined no real production communication chain, issued insurance policy, claim file or operational system. No insurer adoption, premium effect or claims outcome, and no external validation of the method, was found in the sources reviewed. Full endorsement text was not examined. Moffatt was read from the primary decision; no later reversal was found in the searches performed.